{
  const w = 680, h = 180;
  const svg = d3.create("svg").attr("width", w).attr("height", h)
    .style("font-family", "inherit");

  const rows = [
    { label: "Alchemy", left: "Circle + materials", right: "Construct", color: "#e8a317" },
    { label: "Data Science", left: "Data + assumptions", right: "Output", color: "#3b82f6" }
  ];

  const boxW = 200, boxH = 48, arrowY = boxH / 2;
  const leftX = 30, midX = 290, rightX = 450;

  rows.forEach(({ left, right, color, label }, i) => {
    const y = 20 + i * 90;

    // label
    svg.append("text").attr("x", leftX).attr("y", y - 6)
      .attr("font-size", 13).attr("fill", "#888").text(label);

    // left box
    svg.append("rect").attr("x", leftX).attr("y", y)
      .attr("width", boxW).attr("height", boxH).attr("rx", 8)
      .attr("fill", color + "22").attr("stroke", color).attr("stroke-width", 1.5);
    svg.append("text").attr("x", leftX + boxW / 2).attr("y", y + boxH / 2 + 5)
      .attr("text-anchor", "middle").attr("font-size", 14).attr("fill", "#222")
      .text(left);

    // arrow
    const ax1 = leftX + boxW + 6, ax2 = rightX - 6;
    svg.append("line").attr("x1", ax1).attr("y1", y + arrowY)
      .attr("x2", ax2 - 10).attr("y2", y + arrowY)
      .attr("stroke", color).attr("stroke-width", 2);
    svg.append("polygon")
      .attr("points", `${ax2},${y + arrowY} ${ax2 - 10},${y + arrowY - 5} ${ax2 - 10},${y + arrowY + 5}`)
      .attr("fill", color);

    // middle label
    svg.append("text").attr("x", (ax1 + ax2) / 2).attr("y", y + arrowY - 7)
      .attr("text-anchor", "middle").attr("font-size", 12).attr("fill", color)
      .text(i === 0 ? "alchemy" : "model");

    // right box
    svg.append("rect").attr("x", rightX).attr("y", y)
      .attr("width", boxW).attr("height", boxH).attr("rx", 8)
      .attr("fill", color + "22").attr("stroke", color).attr("stroke-width", 1.5);
    svg.append("text").attr("x", rightX + boxW / 2).attr("y", y + boxH / 2 + 5)
      .attr("text-anchor", "middle").attr("font-size", 14).attr("fill", "#222")
      .text(right);
  });

  return svg.node();
}Week 4 — Models
IAT 461 / 882 · Data Science for Human-Centered Systems · Summer 2026 · Alireza Karduni
Models
Full Metal Alchemist
The Transmutation Circle
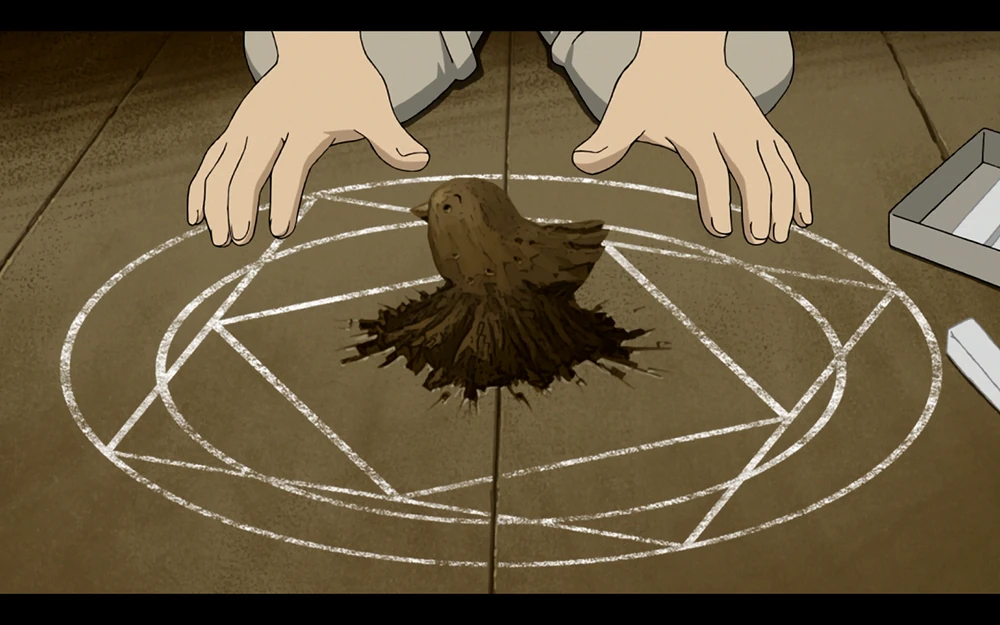
- In Fullmetal Alchemist, alchemists draw a transmutation circle
- It encodes rules and assumptions about how matter should transform
- Add materials. Activate. The alchemy executes — precisely, faithfully
- No judgment. No wisdom. Just the circle.
The Circle Does Exactly What You Drew
- The construct that emerges is entirely determined by the circle and the materials
- A flawed circle → a flawed construct
- The alchemy doesn’t know what you meant — only what you wrote
- Extraordinary power. Zero discretion.
Data Scientists Draw Circles Too
We call ours models.
What Does a Model Actually Do?
A model takes data and does something useful with it:
- Summarize — describe patterns in the data
- Explain — understand why something happens
- Predict — forecast unseen outcomes
- Classify — assign categories to new observations
Same general structure every time: inputs → model → output
Equivalent Exchange
- Whatever wisdom comes out was in the data and assumptions you put in
- The model doesn’t generate insight from nothing
- Wrong assumptions → wrong output, faithfully computed
- Garbage in, garbage out — is just equivalent exchange
Hypotheses and Models Are Not the Same Thing
- A hypothesis is a verbal conjecture:
“Screen time harms wellbeing” - It is vague. Untestable as stated.
- A model is a precise, executable construct
- You need a model to test a hypothesis — but they are not the same thing
Hypotheses and Models Are Not the Same Thing
html`<svg width="680" height="260" font-family="inherit" font-size="14">

  <!-- Column headers -->
  <text x="120" y="30" text-anchor="middle" fill="#6366f1" font-weight="bold" font-size="13">Hypothesis</text>
  <text x="360" y="30" text-anchor="middle" fill="#0ea5e9" font-weight="bold" font-size="13">Process Model</text>
  <text x="590" y="30" text-anchor="middle" fill="#10b981" font-weight="bold" font-size="13">Statistical Model</text>

  <!-- Hypothesis box -->
  <rect x="30" y="90" width="180" height="70" rx="8" fill="#ede9fe" stroke="#6366f1" stroke-width="2"/>
  <text x="120" y="120" text-anchor="middle" fill="#4338ca" font-weight="bold">Screen time</text>
  <text x="120" y="140" text-anchor="middle" fill="#4338ca" font-weight="bold">harms wellbeing</text>

</svg>`
Hypotheses and Models Are Not the Same Thing
html`<svg width="680" height="260" font-family="inherit" font-size="14">

  <!-- Column headers -->
  <text x="120" y="30" text-anchor="middle" fill="#6366f1" font-weight="bold" font-size="13">Hypothesis</text>
  <text x="360" y="30" text-anchor="middle" fill="#0ea5e9" font-weight="bold" font-size="13">Process Model</text>
  <text x="590" y="30" text-anchor="middle" fill="#10b981" font-weight="bold" font-size="13">Statistical Model</text>

  <!-- Hypothesis box -->
  <rect x="30" y="90" width="180" height="70" rx="8" fill="#ede9fe" stroke="#6366f1" stroke-width="2"/>
  <text x="120" y="120" text-anchor="middle" fill="#4338ca" font-weight="bold">Screen time</text>
  <text x="120" y="140" text-anchor="middle" fill="#4338ca" font-weight="bold">harms wellbeing</text>

  <!-- Process model boxes -->
  <rect x="270" y="55" width="180" height="50" rx="8" fill="#e0f2fe" stroke="#0ea5e9" stroke-width="1.5"/>
  <text x="360" y="76" text-anchor="middle" fill="#0369a1" font-weight="bold">Reduce daily</text>
  <text x="360" y="94" text-anchor="middle" fill="#0369a1" font-weight="bold">usage time</text>

  <rect x="270" y="145" width="180" height="50" rx="8" fill="#e0f2fe" stroke="#0ea5e9" stroke-width="1.5"/>
  <text x="360" y="166" text-anchor="middle" fill="#0369a1" font-weight="bold">Replace usage with</text>
  <text x="360" y="184" text-anchor="middle" fill="#0369a1" font-weight="bold">other activities</text>

  <!-- Arrows: hypothesis → process models -->
  <line x1="210" y1="115" x2="268" y2="85" stroke="#6366f1" stroke-width="1.5"/>
  <polygon points="268,85 258,82 261,93" fill="#6366f1"/>

  <line x1="210" y1="135" x2="268" y2="163" stroke="#6366f1" stroke-width="1.5"/>
  <polygon points="268,163 258,157 262,168" fill="#6366f1"/>

</svg>`
Hypotheses and Models Are Not the Same Thing
html`<svg width="680" height="260" font-family="inherit" font-size="14">

  <!-- Column headers -->
  <text x="120" y="30" text-anchor="middle" fill="#6366f1" font-weight="bold" font-size="13">Hypothesis</text>
  <text x="360" y="30" text-anchor="middle" fill="#0ea5e9" font-weight="bold" font-size="13">Process Model</text>
  <text x="590" y="30" text-anchor="middle" fill="#10b981" font-weight="bold" font-size="13">Statistical Model</text>

  <!-- Hypothesis box -->
  <rect x="30" y="90" width="180" height="70" rx="8" fill="#ede9fe" stroke="#6366f1" stroke-width="2"/>
  <text x="120" y="120" text-anchor="middle" fill="#4338ca" font-weight="bold">Screen time</text>
  <text x="120" y="140" text-anchor="middle" fill="#4338ca" font-weight="bold">harms wellbeing</text>

  <!-- Process model boxes -->
  <rect x="270" y="55" width="180" height="50" rx="8" fill="#e0f2fe" stroke="#0ea5e9" stroke-width="1.5"/>
  <text x="360" y="76" text-anchor="middle" fill="#0369a1" font-weight="bold">Reduce daily</text>
  <text x="360" y="94" text-anchor="middle" fill="#0369a1" font-weight="bold">usage time</text>

  <rect x="270" y="145" width="180" height="50" rx="8" fill="#e0f2fe" stroke="#0ea5e9" stroke-width="1.5"/>
  <text x="360" y="166" text-anchor="middle" fill="#0369a1" font-weight="bold">Replace usage with</text>
  <text x="360" y="184" text-anchor="middle" fill="#0369a1" font-weight="bold">other activities</text>

  <!-- Arrows: hypothesis → process models -->
  <line x1="210" y1="115" x2="268" y2="85" stroke="#6366f1" stroke-width="1.5"/>
  <polygon points="268,85 258,82 261,93" fill="#6366f1"/>

  <line x1="210" y1="135" x2="268" y2="163" stroke="#6366f1" stroke-width="1.5"/>
  <polygon points="268,163 258,157 262,168" fill="#6366f1"/>

  <!-- Statistical model boxes -->
  <rect x="500" y="30" width="165" height="45" rx="8" fill="#d1fae5" stroke="#10b981" stroke-width="1.5"/>
  <text x="582" y="50" text-anchor="middle" fill="#065f46" font-weight="bold">Linear regression</text>
  <text x="582" y="67" text-anchor="middle" fill="#065f46" font-size="12">on usage hours</text>

  <rect x="500" y="105" width="165" height="45" rx="8" fill="#d1fae5" stroke="#10b981" stroke-width="1.5"/>
  <text x="582" y="125" text-anchor="middle" fill="#065f46" font-weight="bold">Time-series</text>
  <text x="582" y="142" text-anchor="middle" fill="#065f46" font-size="12">model</text>

  <rect x="500" y="180" width="165" height="45" rx="8" fill="#d1fae5" stroke="#10b981" stroke-width="1.5"/>
  <text x="582" y="200" text-anchor="middle" fill="#065f46" font-weight="bold">Survey scale</text>
  <text x="582" y="217" text-anchor="middle" fill="#065f46" font-size="12">comparison</text>

  <!-- Arrows: process → statistical -->
  <line x1="450" y1="75" x2="498" y2="55" stroke="#0ea5e9" stroke-width="1.5"/>
  <polygon points="498,55 488,52 491,63" fill="#0ea5e9"/>

  <line x1="450" y1="80" x2="498" y2="120" stroke="#0ea5e9" stroke-width="1.5"/>
  <polygon points="498,120 488,114 492,125" fill="#0ea5e9"/>

  <line x1="450" y1="168" x2="498" y2="130" stroke="#0ea5e9" stroke-width="1.5"/>
  <polygon points="498,130 488,127 491,138" fill="#0ea5e9"/>

  <line x1="450" y1="172" x2="498" y2="197" stroke="#0ea5e9" stroke-width="1.5"/>
  <polygon points="498,197 488,191 492,202" fill="#0ea5e9"/>

</svg>`
Hypotheses and Models Are Not the Same Thing
html`<svg width="680" height="260" font-family="inherit" font-size="14">

  <!-- Column headers -->
  <text x="120" y="30" text-anchor="middle" fill="#6366f1" font-weight="bold" font-size="13">Hypothesis</text>
  <text x="360" y="30" text-anchor="middle" fill="#0ea5e9" font-weight="bold" font-size="13">Process Model</text>
  <text x="590" y="30" text-anchor="middle" fill="#10b981" font-weight="bold" font-size="13">Statistical Model</text>

  <!-- Hypothesis boxes — now two -->
  <rect x="30" y="60" width="180" height="60" rx="8" fill="#ede9fe" stroke="#6366f1" stroke-width="2"/>
  <text x="120" y="85" text-anchor="middle" fill="#4338ca" font-weight="bold">Screen time</text>
  <text x="120" y="105" text-anchor="middle" fill="#4338ca" font-weight="bold">harms wellbeing</text>

  <rect x="30" y="155" width="180" height="60" rx="8" fill="#ede9fe" stroke="#6366f1" stroke-width="2"/>
  <text x="120" y="178" text-anchor="middle" fill="#4338ca" font-weight="bold">Passive use is worse</text>
  <text x="120" y="198" text-anchor="middle" fill="#4338ca" font-weight="bold">than active use</text>

  <!-- Process model boxes -->
  <rect x="270" y="55" width="180" height="50" rx="8" fill="#e0f2fe" stroke="#0ea5e9" stroke-width="1.5"/>
  <text x="360" y="76" text-anchor="middle" fill="#0369a1" font-weight="bold">Reduce daily</text>
  <text x="360" y="94" text-anchor="middle" fill="#0369a1" font-weight="bold">usage time</text>

  <rect x="270" y="145" width="180" height="50" rx="8" fill="#e0f2fe" stroke="#0ea5e9" stroke-width="1.5"/>
  <text x="360" y="166" text-anchor="middle" fill="#0369a1" font-weight="bold">Replace usage with</text>
  <text x="360" y="184" text-anchor="middle" fill="#0369a1" font-weight="bold">other activities</text>

  <!-- Arrows hyp → process -->
  <line x1="210" y1="88" x2="268" y2="78" stroke="#6366f1" stroke-width="1.5"/>
  <polygon points="268,78 258,75 261,86" fill="#6366f1"/>

  <line x1="210" y1="100" x2="268" y2="163" stroke="#6366f1" stroke-width="1.5"/>
  <polygon points="268,163 258,157 262,168" fill="#6366f1"/>

  <line x1="210" y1="178" x2="268" y2="85" stroke="#6366f1" stroke-width="1.5"/>
  <polygon points="268,85 258,82 261,93" fill="#6366f1"/>

  <line x1="210" y1="185" x2="268" y2="168" stroke="#6366f1" stroke-width="1.5"/>
  <polygon points="268,168 258,162 262,173" fill="#6366f1"/>

  <!-- Statistical model boxes -->
  <rect x="500" y="30" width="165" height="45" rx="8" fill="#d1fae5" stroke="#10b981" stroke-width="1.5"/>
  <text x="582" y="50" text-anchor="middle" fill="#065f46" font-weight="bold">Linear regression</text>
  <text x="582" y="67" text-anchor="middle" fill="#065f46" font-size="12">on usage hours</text>

  <rect x="500" y="105" width="165" height="45" rx="8" fill="#d1fae5" stroke="#10b981" stroke-width="1.5"/>
  <text x="582" y="125" text-anchor="middle" fill="#065f46" font-weight="bold">Time-series</text>
  <text x="582" y="142" text-anchor="middle" fill="#065f46" font-size="12">model</text>

  <rect x="500" y="180" width="165" height="45" rx="8" fill="#d1fae5" stroke="#10b981" stroke-width="1.5"/>
  <text x="582" y="200" text-anchor="middle" fill="#065f46" font-weight="bold">Survey scale</text>
  <text x="582" y="217" text-anchor="middle" fill="#065f46" font-size="12">comparison</text>

  <!-- Arrows process → statistical -->
  <line x1="450" y1="75" x2="498" y2="55" stroke="#0ea5e9" stroke-width="1.5"/>
  <polygon points="498,55 488,52 491,63" fill="#0ea5e9"/>

  <line x1="450" y1="80" x2="498" y2="120" stroke="#0ea5e9" stroke-width="1.5"/>
  <polygon points="498,120 488,114 492,125" fill="#0ea5e9"/>

  <line x1="450" y1="168" x2="498" y2="130" stroke="#0ea5e9" stroke-width="1.5"/>
  <polygon points="498,130 488,127 491,138" fill="#0ea5e9"/>

  <line x1="450" y1="172" x2="498" y2="197" stroke="#0ea5e9" stroke-width="1.5"/>
  <polygon points="498,197 488,191 492,202" fill="#0ea5e9"/>

  <!-- Key insight label -->
  <rect x="30" y="228" width="620" height="28" rx="6" fill="#fef9c3" stroke="#ca8a04" stroke-width="1"/>
  <text x="340" y="247" text-anchor="middle" fill="#78350f" font-size="13">
    The same statistical model is consistent with multiple hypotheses — rejecting it proves nothing
  </text>

</svg>`
Hypotheses and Models Are Not the Same Thing
- The same statistical model can be consistent with completely different hypotheses
- Rejecting a model does not reject the hypothesis
- Confirming a model does not confirm the hypothesis
- The mapping runs in both directions — many-to-many
Failing to reject the null doesn’t mean the null is true
The Implication: Stay Humble
{
  const w = 680, h = 160;
  const svg = d3.create("svg").attr("width", w).attr("height", h)
    .style("font-family", "inherit");

  const items = [
    { label: "Hypothesis", sub: "vague, verbal", color: "#6366f1", x: 30 },
    { label: "Model",      sub: "precise, executable", color: "#0ea5e9", x: 260 },
    { label: "Evidence",   sub: "data observations", color: "#10b981", x: 490 },
  ];

  items.forEach(({ label, sub, color, x }) => {
    svg.append("rect").attr("x", x).attr("y", 40)
      .attr("width", 170).attr("height", 80).attr("rx", 10)
      .attr("fill", color + "18").attr("stroke", color).attr("stroke-width", 2);
    svg.append("text").attr("x", x + 85).attr("y", 76)
      .attr("text-anchor", "middle").attr("font-size", 15)
      .attr("font-weight", "bold").attr("fill", color).text(label);
    svg.append("text").attr("x", x + 85).attr("y", 100)
      .attr("text-anchor", "middle").attr("font-size", 12).attr("fill", "#555").text(sub);
  });

  // arrows
  [[200, 260], [430, 490]].forEach(([x1, x2], i) => {
    const colors = ["#6366f1", "#0ea5e9"];
    svg.append("line").attr("x1", x1).attr("y1", 80).attr("x2", x2 - 8).attr("y2", 80)
      .attr("stroke", colors[i]).attr("stroke-width", 2).attr("stroke-dasharray", "5,4");
    svg.append("polygon")
      .attr("points", `${x2},80 ${x2 - 10},75 ${x2 - 10},85`)
      .attr("fill", colors[i]);
  });

  // warning labels on arrows
  [{ x: 228, t: "many possible" }, { x: 458, t: "many consistent" }].forEach(({ x, t }) => {
    svg.append("text").attr("x", x).attr("y", 70)
      .attr("text-anchor", "middle").attr("font-size", 11).attr("fill", "#999")
      .attr("font-style", "italic").text(t);
  });

  return svg.node();
}- Evidence tests a model, not a hypothesis directly
- Statistical models are lenses, not verdicts
- Always ask: what other hypotheses is my model consistent with?
All Models Are Wrong
“All models are wrong, but some are useful.”
— George Box
- No model is the world — all are simplifications
- The question is never “is this model true?”
- The question is: “is it useful — and does it know its own limits?”
- A model confident beyond its design is the most dangerous kind
A Taxonomy of Models
Models Come in Many Flavors
- Not all models do the same thing
- Before choosing a model, you need to know what you’re asking it to do
- Two key questions:
- What is the goal — explain or predict?
- Where does the structure come from — theory or data?
The Modeling Space
html`<svg width="660" height="380" font-family="inherit" font-size="14">
  <line x1="80" y1="190" x2="590" y2="190" stroke="#ccc" stroke-width="1.5"/>
  <line x1="330" y1="30" x2="330" y2="360" stroke="#ccc" stroke-width="1.5"/>
  <text x="88" y="184" fill="#888" font-size="13">← Theory-driven</text>
  <text x="500" y="184" fill="#888" font-size="13">Data-driven →</text>
  <text x="330" y="22" text-anchor="middle" fill="#888" font-size="13">↑ Explanatory</text>
  <text x="330" y="375" text-anchor="middle" fill="#888" font-size="13">↓ Predictive</text>
</svg>`
The Modeling Space
html`<svg width="660" height="380" font-family="inherit" font-size="14">
  <line x1="80" y1="190" x2="590" y2="190" stroke="#ccc" stroke-width="1.5"/>
  <line x1="330" y1="30" x2="330" y2="360" stroke="#ccc" stroke-width="1.5"/>
  <text x="88" y="184" fill="#888" font-size="13">← Theory-driven</text>
  <text x="500" y="184" fill="#888" font-size="13">Data-driven →</text>
  <text x="330" y="22" text-anchor="middle" fill="#888" font-size="13">↑ Explanatory</text>
  <text x="330" y="375" text-anchor="middle" fill="#888" font-size="13">↓ Predictive</text>

  <!-- Q1: Theory + Explanatory -->
  <rect x="95" y="45" width="220" height="55" rx="8" fill="#ede9fe" stroke="#7c3aed" stroke-width="1.5"/>
  <text x="205" y="69" text-anchor="middle" fill="#4c1d95" font-weight="bold">Epidemiological models</text>
  <text x="205" y="88" text-anchor="middle" fill="#6d28d9" font-size="12">SIR — why disease spreads</text>
</svg>`
The Modeling Space
html`<svg width="660" height="380" font-family="inherit" font-size="14">
  <line x1="80" y1="190" x2="590" y2="190" stroke="#ccc" stroke-width="1.5"/>
  <line x1="330" y1="30" x2="330" y2="360" stroke="#ccc" stroke-width="1.5"/>
  <text x="88" y="184" fill="#888" font-size="13">← Theory-driven</text>
  <text x="500" y="184" fill="#888" font-size="13">Data-driven →</text>
  <text x="330" y="22" text-anchor="middle" fill="#888" font-size="13">↑ Explanatory</text>
  <text x="330" y="375" text-anchor="middle" fill="#888" font-size="13">↓ Predictive</text>

  <!-- Q1: Theory + Explanatory -->
  <rect x="95" y="45" width="220" height="55" rx="8" fill="#ede9fe" stroke="#7c3aed" stroke-width="1.5"/>
  <text x="205" y="69" text-anchor="middle" fill="#4c1d95" font-weight="bold">Epidemiological models</text>
  <text x="205" y="88" text-anchor="middle" fill="#6d28d9" font-size="12">SIR — why disease spreads</text>

  <!-- Q2: Data + Explanatory -->
  <rect x="345" y="45" width="220" height="55" rx="8" fill="#dbeafe" stroke="#2563eb" stroke-width="1.5"/>
  <text x="455" y="69" text-anchor="middle" fill="#1e3a8a" font-weight="bold">Regression analysis</text>
  <text x="455" y="88" text-anchor="middle" fill="#1d4ed8" font-size="12">does screen time affect mood?</text>
</svg>`
The Modeling Space
html`<svg width="660" height="380" font-family="inherit" font-size="14">
  <line x1="80" y1="190" x2="590" y2="190" stroke="#ccc" stroke-width="1.5"/>
  <line x1="330" y1="30" x2="330" y2="360" stroke="#ccc" stroke-width="1.5"/>
  <text x="88" y="184" fill="#888" font-size="13">← Theory-driven</text>
  <text x="500" y="184" fill="#888" font-size="13">Data-driven →</text>
  <text x="330" y="22" text-anchor="middle" fill="#888" font-size="13">↑ Explanatory</text>
  <text x="330" y="375" text-anchor="middle" fill="#888" font-size="13">↓ Predictive</text>

  <!-- Q1: Theory + Explanatory -->
  <rect x="95" y="45" width="220" height="55" rx="8" fill="#ede9fe" stroke="#7c3aed" stroke-width="1.5"/>
  <text x="205" y="69" text-anchor="middle" fill="#4c1d95" font-weight="bold">Epidemiological models</text>
  <text x="205" y="88" text-anchor="middle" fill="#6d28d9" font-size="12">SIR — why disease spreads</text>

  <!-- Q2: Data + Explanatory -->
  <rect x="345" y="45" width="220" height="55" rx="8" fill="#dbeafe" stroke="#2563eb" stroke-width="1.5"/>
  <text x="455" y="69" text-anchor="middle" fill="#1e3a8a" font-weight="bold">Regression analysis</text>
  <text x="455" y="88" text-anchor="middle" fill="#1d4ed8" font-size="12">does screen time affect mood?</text>

  <!-- Q3: Theory + Predictive -->
  <rect x="95" y="295" width="220" height="55" rx="8" fill="#fef9c3" stroke="#ca8a04" stroke-width="1.5"/>
  <text x="205" y="319" text-anchor="middle" fill="#78350f" font-weight="bold">Physics simulations</text>
  <text x="205" y="338" text-anchor="middle" fill="#92400e" font-size="12">trajectory from equations</text>

  <!-- Q4: Data + Predictive -->
  <rect x="345" y="295" width="220" height="55" rx="8" fill="#dcfce7" stroke="#16a34a" stroke-width="1.5"/>
  <text x="455" y="319" text-anchor="middle" fill="#14532d" font-weight="bold">ML classifiers</text>
  <text x="455" y="338" text-anchor="middle" fill="#166534" font-size="12">predict churn from behaviour</text>
</svg>`
Explanatory vs. Predictive
- Explanatory — why does something happen?
- We care about the relationship between variables
- Interpretability matters
- Example: does streaming duration cause viewer drop-off?
- Predictive — what comes next?
- We care about accuracy on unseen data
- The mechanism can be a black box
- Example: which sessions will end in the next 5 minutes?
The Same Question, Two Models
html`<svg width="660" height="200" font-family="inherit" font-size="14">

  <!-- Explanatory box -->
  <rect x="20" y="30" width="280" height="140" rx="10" fill="#ede9fe" stroke="#7c3aed" stroke-width="2"/>
  <text x="160" y="58" text-anchor="middle" font-weight="bold" fill="#4c1d95" font-size="15">Explanatory Model</text>
  <text x="160" y="82" text-anchor="middle" fill="#5b21b6">"Does stream length</text>
  <text x="160" y="100" text-anchor="middle" fill="#5b21b6">affect viewer drop-off?"</text>
  <text x="160" y="128" text-anchor="middle" fill="#7c3aed" font-size="12">→ coefficients, significance</text>
  <text x="160" y="148" text-anchor="middle" fill="#7c3aed" font-size="12">→ interpretability is the goal</text>

  <!-- divider -->
  <text x="330" y="108" text-anchor="middle" fill="#bbb" font-size="28">vs</text>

  <!-- Predictive box -->
  <rect x="360" y="30" width="280" height="140" rx="10" fill="#dcfce7" stroke="#16a34a" stroke-width="2"/>
  <text x="500" y="58" text-anchor="middle" font-weight="bold" fill="#14532d" font-size="15">Predictive Model</text>
  <text x="500" y="82" text-anchor="middle" fill="#166534">"Which session will</text>
  <text x="500" y="100" text-anchor="middle" fill="#166534">end in 5 minutes?"</text>
  <text x="500" y="128" text-anchor="middle" fill="#16a34a" font-size="12">→ accuracy on unseen data</text>
  <text x="500" y="148" text-anchor="middle" fill="#16a34a" font-size="12">→ mechanism can be hidden</text>

</svg>`
Same phenomenon. Different questions. Different models.
Structure: Theory-Driven vs. Data-Driven
- Theory-driven — structure comes from domain knowledge
- You encode assumptions about how the world works
- Interpretable by design, but brittle outside its assumptions
- Example: an SIR model assumes people move through Susceptible → Infected → Recovered
- Data-driven — structure is learned from data
- The model finds patterns without being told what to look for
- Flexible and powerful, but can fail silently
- Example: a neural net predicting engagement from 200 features
Deterministic vs. Stochastic
- Deterministic — same input always gives the same output
- Example: F = ma — given force and mass, acceleration is fixed
- Stochastic — output is a probability distribution over possible outcomes
- Example: 70% chance of rain tomorrow
- Demanding a single point prediction from an uncertain process destroys information
Why Stochastic Models Matter
html`<svg width="660" height="220" font-family="inherit" font-size="14">

  <!-- Deterministic side -->
  <rect x="20" y="20" width="280" height="180" rx="10" fill="#fee2e2" stroke="#dc2626" stroke-width="2"/>
  <text x="160" y="50" text-anchor="middle" font-weight="bold" fill="#7f1d1d" font-size="15">Deterministic Answer</text>
  <text x="160" y="85" text-anchor="middle" fill="#991b1b" font-size="13">"It will rain tomorrow."</text>

  <text x="160" y="125" text-anchor="middle" fill="#b91c1c" font-size="12">Single point prediction</text>
  <text x="160" y="145" text-anchor="middle" fill="#b91c1c" font-size="12">No sense of uncertainty</text>
  <text x="160" y="165" text-anchor="middle" fill="#b91c1c" font-size="12">Right or wrong — nothing in between</text>

  <!-- vs -->
  <text x="330" y="118" text-anchor="middle" fill="#bbb" font-size="28">vs</text>

  <!-- Stochastic side -->
  <rect x="360" y="20" width="280" height="180" rx="10" fill="#dcfce7" stroke="#16a34a" stroke-width="2"/>
  <text x="500" y="50" text-anchor="middle" font-weight="bold" fill="#14532d" font-size="15">Stochastic Answer</text>
  <text x="500" y="85" text-anchor="middle" fill="#166534" font-size="13">"70% chance of rain."</text>

  <text x="500" y="125" text-anchor="middle" fill="#15803d" font-size="12">Distribution over outcomes</text>
  <text x="500" y="145" text-anchor="middle" fill="#15803d" font-size="12">Captures uncertainty honestly</text>
  <text x="500" y="165" text-anchor="middle" fill="#15803d" font-size="12">Can be calibrated and improved</text>

</svg>`
A model that says “I’m 70% sure” is more useful than one forced to say “yes” or “no.”
Classifier vs. Regressor
The output type determines everything downstream.
- Classifier — output is a category
- Is this comment toxic? → Yes / No
- Which genre does this stream belong to? → Gaming / IRL / Music
- Regressor — output is a number
- How many viewers will tune in? → 4,200
- How toxic is this comment? → 0.73
- Different output types → different designs, different failure modes, different evaluation metrics
Classifier vs. Regressor
html`<svg width="660" height="230" font-family="inherit" font-size="14">

  <!-- shared input -->
  <rect x="240" y="90" width="170" height="50" rx="8" fill="#f1f5f9" stroke="#94a3b8" stroke-width="1.5"/>
  <text x="325" y="110" text-anchor="middle" fill="#334155" font-weight="bold">Input</text>
  <text x="325" y="130" text-anchor="middle" fill="#64748b" font-size="12">stream session data</text>

  <!-- arrow to classifier -->
  <line x1="240" y1="105" x2="155" y2="65" stroke="#7c3aed" stroke-width="1.5"/>
  <polygon points="150,60 160,58 158,70" fill="#7c3aed"/>

  <!-- classifier box -->
  <rect x="20" y="20" width="200" height="55" rx="8" fill="#ede9fe" stroke="#7c3aed" stroke-width="2"/>
  <text x="120" y="43" text-anchor="middle" fill="#4c1d95" font-weight="bold">Classifier</text>
  <text x="120" y="63" text-anchor="middle" fill="#6d28d9" font-size="12">→ "Gaming" / "IRL" / "Music"</text>

  <!-- arrow to regressor -->
  <line x1="415" y1="105" x2="500" y2="65" stroke="#0ea5e9" stroke-width="1.5"/>
  <polygon points="505,60 495,58 497,70" fill="#0ea5e9"/>

  <!-- regressor box -->
  <rect x="440" y="20" width="200" height="55" rx="8" fill="#e0f2fe" stroke="#0ea5e9" stroke-width="2"/>
  <text x="540" y="43" text-anchor="middle" fill="#0c4a6e" font-weight="bold">Regressor</text>
  <text x="540" y="63" text-anchor="middle" fill="#0369a1" font-size="12">→ 4,200 viewers</text>

  <!-- evaluation labels -->
  <rect x="20" y="150" width="200" height="60" rx="8" fill="#f5f3ff" stroke="#a78bfa" stroke-width="1"/>
  <text x="120" y="172" text-anchor="middle" fill="#5b21b6" font-size="12" font-weight="bold">Evaluated by:</text>
  <text x="120" y="192" text-anchor="middle" fill="#6d28d9" font-size="12">accuracy, precision, recall</text>
  <text x="120" y="208" text-anchor="middle" fill="#6d28d9" font-size="12">confusion matrix</text>

  <rect x="440" y="150" width="200" height="60" rx="8" fill="#f0f9ff" stroke="#7dd3fc" stroke-width="1"/>
  <text x="540" y="172" text-anchor="middle" fill="#075985" font-size="12" font-weight="bold">Evaluated by:</text>
  <text x="540" y="192" text-anchor="middle" fill="#0369a1" font-size="12">MSE, RMSE, MAE</text>
  <text x="540" y="208" text-anchor="middle" fill="#0369a1" font-size="12">R²</text>

</svg>`
Black Box vs. Interpretable
- Interpretable — you can read off why the model made a decision
- Linear regression: each coefficient has a clear meaning
- Decision tree: follow the branches
- Random forests:
- Black box — the model works, but you can’t easily explain how
- Neural networks: millions of weights, no clear narrative
- This matters enormously in human-centered systems — can you explain the decision to the person it affects?
Choosing a Model Type
- There is no universally best model — the right choice depends on:
- What is the goal? Explain or predict?
- How much data do you have? Theory fills the gap when data is scarce
- Does uncertainty matter? Use stochastic models when it does
- Will someone be affected by the decision? Interpretability may be non-negotiable
- The taxonomy is a thinking tool, not a checklist
Evaluating Models
Did the Model Actually Work?
- Building a model is only half the job
- The harder question: how do we know if it worked?
- The answer depends entirely on what we asked the model to do
- Evaluation is not one-size-fits-all
Two Worlds of Evaluation
html`<svg width="660" height="200" font-family="inherit" font-size="14">

  <!-- Left box: explanation -->
  <rect x="20" y="30" width="285" height="140" rx="10" fill="#ede9fe" stroke="#7c3aed" stroke-width="2"/>
  <text x="163" y="62" text-anchor="middle" font-weight="bold" fill="#4c1d95" font-size="15">Statistical Explanation</text>
  <text x="163" y="90" text-anchor="middle" fill="#6d28d9">"Why does this happen?"</text>
  <text x="163" y="118" text-anchor="middle" fill="#7c3aed" font-size="12">→ Does the model fit the data?</text>
  <text x="163" y="138" text-anchor="middle" fill="#7c3aed" font-size="12">→ Are the relationships meaningful?</text>
  <text x="163" y="158" text-anchor="middle" fill="#7c3aed" font-size="12">→ R², residuals, significance</text>

  <!-- Right box: prediction -->
  <rect x="355" y="30" width="285" height="140" rx="10" fill="#dcfce7" stroke="#16a34a" stroke-width="2"/>
  <text x="498" y="62" text-anchor="middle" font-weight="bold" fill="#14532d" font-size="15">ML Prediction</text>
  <text x="498" y="90" text-anchor="middle" fill="#166534">"Does it generalize?"</text>
  <text x="498" y="118" text-anchor="middle" fill="#16a34a" font-size="12">→ Does it work on unseen data?</text>
  <text x="498" y="138" text-anchor="middle" fill="#16a34a" font-size="12">→ Classification or regression?</text>
  <text x="498" y="158" text-anchor="middle" fill="#16a34a" font-size="12">→ Accuracy, precision, MSE…</text>

</svg>`
Before You Run Any Stats: Define the Question
- Every evaluation starts before the model, not after
- You need to define:
- What is the construct you are measuring?
- How is it operationalized in the data?
- What would a meaningful result look like?
- Running a model without this is like measuring with a broken ruler
The Evaluation Chain
html`<svg width="660" height="150" font-family="inherit" font-size="13">

  <!-- Box 1: Question -->
  <rect x="10" y="20" width="140" height="70" rx="8" fill="#f1f5f9" stroke="#94a3b8" stroke-width="1.5"/>
  <text x="80" y="48" text-anchor="middle" fill="#334155" font-weight="bold">Question</text>
  <text x="80" y="66" text-anchor="middle" fill="#64748b" font-size="11">what do we</text>
  <text x="80" y="80" text-anchor="middle" fill="#64748b" font-size="11">want to know?</text>

  <!-- Arrow 1 -->
  <line x1="150" y1="55" x2="173" y2="55" stroke="#94a3b8" stroke-width="1.5"/>
  <polygon points="174,55 164,50 164,60" fill="#94a3b8"/>

  <!-- Box 2: Construct -->
  <rect x="175" y="20" width="140" height="70" rx="8" fill="#f1f5f9" stroke="#94a3b8" stroke-width="1.5"/>
  <text x="245" y="48" text-anchor="middle" fill="#334155" font-weight="bold">Construct</text>
  <text x="245" y="66" text-anchor="middle" fill="#64748b" font-size="11">what concept</text>
  <text x="245" y="80" text-anchor="middle" fill="#64748b" font-size="11">are we measuring?</text>

  <!-- Arrow 2 -->
  <line x1="315" y1="55" x2="338" y2="55" stroke="#94a3b8" stroke-width="1.5"/>
  <polygon points="339,55 329,50 329,60" fill="#94a3b8"/>

  <!-- Box 3: Model -->
  <rect x="340" y="20" width="140" height="70" rx="8" fill="#f1f5f9" stroke="#94a3b8" stroke-width="1.5"/>
  <text x="410" y="48" text-anchor="middle" fill="#334155" font-weight="bold">Model</text>
  <text x="410" y="66" text-anchor="middle" fill="#64748b" font-size="11">how do we</text>
  <text x="410" y="80" text-anchor="middle" fill="#64748b" font-size="11">operationalize it?</text>

  <!-- Arrow 3 -->
  <line x1="480" y1="55" x2="503" y2="55" stroke="#94a3b8" stroke-width="1.5"/>
  <polygon points="504,55 494,50 494,60" fill="#94a3b8"/>

  <!-- Box 4: Interpretation -->
  <rect x="505" y="20" width="145" height="70" rx="8" fill="#f1f5f9" stroke="#94a3b8" stroke-width="1.5"/>
  <text x="577" y="48" text-anchor="middle" fill="#334155" font-weight="bold">Interpretation</text>
  <text x="577" y="66" text-anchor="middle" fill="#64748b" font-size="11">what does the</text>
  <text x="577" y="80" text-anchor="middle" fill="#64748b" font-size="11">output mean?</text>

</svg>`
Skipping any step contaminates everything that follows.
A Concrete Example
Question: Does increased Twitch stream length lead to more viewers dropping off?
- Construct: viewer engagement — but what counts as drop-off?
- Leaving mid-stream? Not returning next session? Both?
- Operationalization: average viewer retention rate per stream, binned by duration
- Model: linear regression — retention ~ duration
- Interpretation: a negative coefficient means longer streams lose viewers on average — but how much matters, and for whom?
Model Fit: How Well Does the Model Explain the Data?
- For explanatory models, the first question is: how much of the variation does the model account for?
- We measure this with R² — the coefficient of determination
- R² = 1 means the model explains all variation in the outcome
- R² = 0 means the model explains nothing
- R² = 0.6 means 60% of the variation in the outcome is explained by the predictors
Visualizing Model Fit
{
  const w = 660, h = 260;
  const svg = d3.create("svg")
    .attr("width", w).attr("height", h)
    .style("font-family", "inherit");

  const pad = { l: 55, r: 30, t: 20, b: 40 };
  const pw = w - pad.l - pad.r;
  const ph = h - pad.t - pad.b;

  // fake data: stream duration vs retention rate
  const data = [
    [30,92],[45,88],[60,84],[75,80],[90,74],[105,70],
    [120,68],[135,62],[150,58],[165,55],[180,50],
    [50,95],[80,78],[100,72],[130,65],[160,52],[40,90],[110,69]
  ];

  const xMin = 25, xMax = 190, yMin = 44, yMax = 100;
  const xS = v => pad.l + (v - xMin) / (xMax - xMin) * pw;
  const yS = v => pad.t + ph - (v - yMin) / (yMax - yMin) * ph;

  // axes
  svg.append("line").attr("x1", pad.l).attr("y1", pad.t + ph)
    .attr("x2", pad.l + pw).attr("y2", pad.t + ph)
    .attr("stroke", "#ccc").attr("stroke-width", 1.5);
  svg.append("line").attr("x1", pad.l).attr("y1", pad.t)
    .attr("x2", pad.l).attr("y2", pad.t + ph)
    .attr("stroke", "#ccc").attr("stroke-width", 1.5);

  // axis labels
  svg.append("text").attr("x", pad.l + pw / 2).attr("y", h - 5)
    .attr("text-anchor", "middle").attr("font-size", 12).attr("fill", "#888")
    .text("Stream Duration (minutes)");
  svg.append("text").attr("x", 14).attr("y", pad.t + ph / 2)
    .attr("text-anchor", "middle").attr("font-size", 12).attr("fill", "#888")
    .attr("transform", `rotate(-90, 14, ${pad.t + ph / 2})`)
    .text("Viewer Retention (%)");

  // regression line y = 100 - 0.28x  (approx)
  const lineX1 = xMin, lineX2 = xMax;
  const lineY1 = 100 - 0.28 * lineX1;
  const lineY2 = 100 - 0.28 * lineX2;

  // residuals
  data.forEach(([x, y]) => {
    const yHat = 100 - 0.28 * x;
    svg.append("line")
      .attr("x1", xS(x)).attr("y1", yS(y))
      .attr("x2", xS(x)).attr("y2", yS(yHat))
      .attr("stroke", "#f97316").attr("stroke-width", 1.2)
      .attr("stroke-dasharray", "3,2");
  });

  // regression line
  svg.append("line")
    .attr("x1", xS(lineX1)).attr("y1", yS(lineY1))
    .attr("x2", xS(lineX2)).attr("y2", yS(lineY2))
    .attr("stroke", "#3b82f6").attr("stroke-width", 2.5);

  // data points
  data.forEach(([x, y]) => {
    svg.append("circle")
      .attr("cx", xS(x)).attr("cy", yS(y))
      .attr("r", 5).attr("fill", "#6366f1")
      .attr("opacity", 0.85);
  });

  // legend
  svg.append("circle").attr("cx", pad.l + 10).attr("cy", pad.t + 12).attr("r", 5).attr("fill", "#6366f1");
  svg.append("text").attr("x", pad.l + 20).attr("y", pad.t + 16).attr("font-size", 12).attr("fill", "#555").text("Observed data");

  svg.append("line").attr("x1", pad.l + 110).attr("y1", pad.t + 12)
    .attr("x2", pad.l + 140).attr("y2", pad.t + 12)
    .attr("stroke", "#3b82f6").attr("stroke-width", 2.5);
  svg.append("text").attr("x", pad.l + 145).attr("y", pad.t + 16).attr("font-size", 12).attr("fill", "#555").text("Model (regression line)");

  svg.append("line").attr("x1", pad.l + 295).attr("y1", pad.t + 8)
    .attr("x2", pad.l + 295).attr("y2", pad.t + 18)
    .attr("stroke", "#f97316").attr("stroke-width", 1.5).attr("stroke-dasharray", "3,2");
  svg.append("text").attr("x", pad.l + 300).attr("y", pad.t + 16).attr("font-size", 12).attr("fill", "#555").text("Residual (error)");

  return svg.node();
}
The residuals (orange dashes) are the gaps between what the model predicts and what actually happened. Smaller residuals → better fit.
Fit Is Not Enough
- A model can fit training data perfectly and still be useless
- If the model is too complex, it memorizes the data instead of learning from it
- Perfect fit on known data + poor performance on new data = overfitting
- This is why explanatory fit metrics alone are not sufficient
- We need a separate strategy for evaluating generalization — how the model performs on data it has never seen
That is what the ML evaluation framework is built to solve.
Evaluating ML Models: Classification
The Core Problem
- Explanatory models ask: does this fit the data I have?
- ML models ask something harder: does this work on data I haven’t seen yet?
- A model that memorizes training data looks perfect — but is useless
- We need a principled way to test generalization
The Train / Test Split
html`<svg width="660" height="160" font-family="inherit" font-size="14">

  <!-- Full dataset bar -->
  <rect x="30" y="30" width="600" height="50" rx="8" fill="#e2e8f0" stroke="#94a3b8" stroke-width="1.5"/>
  <text x="330" y="61" text-anchor="middle" fill="#475569" font-weight="bold">All available data</text>

  <!-- arrow down -->
  <line x1="330" y1="82" x2="330" y2="105" stroke="#94a3b8" stroke-width="1.5"/>
  <polygon points="330,108 325,100 335,100" fill="#94a3b8"/>

  <!-- Train portion -->
  <rect x="30" y="110" width="420" height="40" rx="8" fill="#dbeafe" stroke="#2563eb" stroke-width="2"/>
  <text x="240" y="136" text-anchor="middle" fill="#1e3a8a" font-weight="bold">Training Set (70%)</text>

  <!-- Test portion -->
  <rect x="460" y="110" width="170" height="40" rx="8" fill="#dcfce7" stroke="#16a34a" stroke-width="2"/>
  <text x="545" y="136" text-anchor="middle" fill="#14532d" font-weight="bold">Test Set (30%)</text>

</svg>`- Training set — the model learns from this
- Test set — held back, never touched during training
- Performance on the test set tells you how the model does on unseen data
Why Keep a Test Set?
- A student who memorizes last year’s exam answers will score 100%
- That tells you nothing about whether they learned
- The test set is the exam with new questions
- If you peek at test data during training, you’ve spoiled the exam
- This is the most common mistake in applied ML
Train / Test / Validation — Three Roles
html`<svg width="660" height="175" font-family="inherit" font-size="14">

  <!-- Full dataset bar -->
  <rect x="30" y="20" width="600" height="40" rx="8" fill="#e2e8f0" stroke="#94a3b8" stroke-width="1.5"/>
  <text x="330" y="46" text-anchor="middle" fill="#475569" font-weight="bold">All available data</text>

  <!-- arrow down -->
  <line x1="330" y1="62" x2="330" y2="82" stroke="#94a3b8" stroke-width="1.5"/>
  <polygon points="330,85 325,77 335,77" fill="#94a3b8"/>

  <!-- Train -->
  <rect x="30" y="88" width="330" height="40" rx="8" fill="#dbeafe" stroke="#2563eb" stroke-width="2"/>
  <text x="195" y="114" text-anchor="middle" fill="#1e3a8a" font-weight="bold">Training Set (60%)</text>

  <!-- Validation -->
  <rect x="370" y="88" width="130" height="40" rx="8" fill="#fef9c3" stroke="#ca8a04" stroke-width="2"/>
  <text x="435" y="114" text-anchor="middle" fill="#78350f" font-weight="bold">Validation (20%)</text>

  <!-- Test -->
  <rect x="510" y="88" width="120" height="40" rx="8" fill="#dcfce7" stroke="#16a34a" stroke-width="2"/>
  <text x="570" y="114" text-anchor="middle" fill="#14532d" font-weight="bold">Test (20%)</text>

  <!-- role labels -->
  <text x="195" y="148" text-anchor="middle" fill="#2563eb" font-size="12">learn from this</text>
  <text x="435" y="148" text-anchor="middle" fill="#b45309" font-size="12">tune and improve</text>
  <text x="570" y="148" text-anchor="middle" fill="#16a34a" font-size="12">final verdict only</text>

  <!-- lock icon hint for test -->
  <text x="570" y="165" text-anchor="middle" fill="#16a34a" font-size="11">🔒 touch once</text>

</svg>`
The validation set is for iterating. The test set is sacred — use it once, at the very end.
Accuracy — The Obvious Metric
- The simplest question: what fraction of predictions were correct?
\[\text{Accuracy} = \frac{\text{correct predictions}}{\text{total predictions}}\]
- Easy to compute, easy to understand
- Example: model predicts viewer will return tomorrow — correct 82 times out of 100 → accuracy = 82%
Why Accuracy Can Lie
- Imagine a rare disease that affects 1% of the population
- A model that always predicts “healthy” — no matter what — gets 99% accuracy
- Is that a good model?
- It has never correctly identified a single sick person
- Accuracy is misleading whenever classes are imbalanced
The Confusion Matrix — Axes
html`<svg width="460" height="300" font-family="inherit" font-size="14">

  <!-- Predicted axis label -->
  <text x="270" y="30" text-anchor="middle" fill="#334155" font-weight="bold" font-size="15">Predicted</text>
  <text x="185" y="68" text-anchor="middle" fill="#64748b">Positive</text>
  <text x="355" y="68" text-anchor="middle" fill="#64748b">Negative</text>

  <!-- Actual axis label -->
  <text x="38" y="175" text-anchor="middle" fill="#334155" font-weight="bold" font-size="15"
        transform="rotate(-90, 38, 175)">Actual</text>
  <text x="80" y="148" text-anchor="middle" fill="#64748b">Positive</text>
  <text x="80" y="238" text-anchor="middle" fill="#64748b">Negative</text>

  <!-- grid lines -->
  <rect x="110" y="78" width="300" height="190" rx="6" fill="none" stroke="#e2e8f0" stroke-width="1.5"/>
  <line x1="110" y1="173" x2="410" y2="173" stroke="#e2e8f0" stroke-width="1.5"/>
  <line x1="260" y1="78"  x2="260" y2="268" stroke="#e2e8f0" stroke-width="1.5"/>

  <!-- empty cells -->
  <rect x="113" y="81"  width="144" height="89" rx="4" fill="#f8fafc"/>
  <rect x="263" y="81"  width="144" height="89" rx="4" fill="#f8fafc"/>
  <rect x="113" y="176" width="144" height="89" rx="4" fill="#f8fafc"/>
  <rect x="263" y="176" width="144" height="89" rx="4" fill="#f8fafc"/>

</svg>`
True Positives & True Negatives
html`<svg width="460" height="300" font-family="inherit" font-size="14">

  <!-- Predicted axis label -->
  <text x="270" y="30" text-anchor="middle" fill="#334155" font-weight="bold" font-size="15">Predicted</text>
  <text x="185" y="68" text-anchor="middle" fill="#64748b">Positive</text>
  <text x="355" y="68" text-anchor="middle" fill="#64748b">Negative</text>

  <!-- Actual axis label -->
  <text x="38" y="175" text-anchor="middle" fill="#334155" font-weight="bold" font-size="15"
        transform="rotate(-90, 38, 175)">Actual</text>
  <text x="80" y="148" text-anchor="middle" fill="#64748b">Positive</text>
  <text x="80" y="238" text-anchor="middle" fill="#64748b">Negative</text>

  <!-- grid -->
  <rect x="110" y="78" width="300" height="190" rx="6" fill="none" stroke="#e2e8f0" stroke-width="1.5"/>
  <line x1="110" y1="173" x2="410" y2="173" stroke="#e2e8f0" stroke-width="1.5"/>
  <line x1="260" y1="78"  x2="260" y2="268" stroke="#e2e8f0" stroke-width="1.5"/>

  <!-- TP -->
  <rect x="113" y="81" width="144" height="89" rx="4" fill="#dcfce7" stroke="#16a34a" stroke-width="1.5"/>
  <text x="185" y="122" text-anchor="middle" fill="#14532d" font-weight="bold" font-size="15">TP</text>
  <text x="185" y="143" text-anchor="middle" fill="#166534" font-size="12">True Positive</text>
  <text x="185" y="160" text-anchor="middle" fill="#166534" font-size="11">correctly said: sick</text>

  <!-- empty FN -->
  <rect x="263" y="81" width="144" height="89" rx="4" fill="#f8fafc"/>

  <!-- empty FP -->
  <rect x="113" y="176" width="144" height="89" rx="4" fill="#f8fafc"/>

  <!-- TN -->
  <rect x="263" y="176" width="144" height="89" rx="4" fill="#dcfce7" stroke="#16a34a" stroke-width="1.5"/>
  <text x="335" y="217" text-anchor="middle" fill="#14532d" font-weight="bold" font-size="15">TN</text>
  <text x="335" y="238" text-anchor="middle" fill="#166534" font-size="12">True Negative</text>
  <text x="335" y="255" text-anchor="middle" fill="#166534" font-size="11">correctly said: healthy</text>

</svg>`
These are the wins — the model got it right in both directions.
False Positives
html`<svg width="460" height="300" font-family="inherit" font-size="14">

  <!-- Predicted axis label -->
  <text x="270" y="30" text-anchor="middle" fill="#334155" font-weight="bold" font-size="15">Predicted</text>
  <text x="185" y="68" text-anchor="middle" fill="#64748b">Positive</text>
  <text x="355" y="68" text-anchor="middle" fill="#64748b">Negative</text>

  <!-- Actual axis label -->
  <text x="38" y="175" text-anchor="middle" fill="#334155" font-weight="bold" font-size="15"
        transform="rotate(-90, 38, 175)">Actual</text>
  <text x="80" y="148" text-anchor="middle" fill="#64748b">Positive</text>
  <text x="80" y="238" text-anchor="middle" fill="#64748b">Negative</text>

  <!-- grid -->
  <rect x="110" y="78" width="300" height="190" rx="6" fill="none" stroke="#e2e8f0" stroke-width="1.5"/>
  <line x1="110" y1="173" x2="410" y2="173" stroke="#e2e8f0" stroke-width="1.5"/>
  <line x1="260" y1="78"  x2="260" y2="268" stroke="#e2e8f0" stroke-width="1.5"/>

  <!-- TP -->
  <rect x="113" y="81" width="144" height="89" rx="4" fill="#dcfce7" stroke="#16a34a" stroke-width="1.5"/>
  <text x="185" y="122" text-anchor="middle" fill="#14532d" font-weight="bold" font-size="15">TP</text>
  <text x="185" y="143" text-anchor="middle" fill="#166534" font-size="12">True Positive</text>
  <text x="185" y="160" text-anchor="middle" fill="#166534" font-size="11">correctly said: sick</text>

  <!-- FN -->
  <rect x="263" y="81" width="144" height="89" rx="4" fill="#f8fafc"/>

  <!-- FP -->
  <rect x="113" y="176" width="144" height="89" rx="4" fill="#fee2e2" stroke="#dc2626" stroke-width="1.5"/>
  <text x="185" y="217" text-anchor="middle" fill="#7f1d1d" font-weight="bold" font-size="15">FP</text>
  <text x="185" y="238" text-anchor="middle" fill="#991b1b" font-size="12">False Positive</text>
  <text x="185" y="255" text-anchor="middle" fill="#991b1b" font-size="11">said sick — actually healthy</text>

  <!-- TN -->
  <rect x="263" y="176" width="144" height="89" rx="4" fill="#dcfce7" stroke="#16a34a" stroke-width="1.5"/>
  <text x="335" y="217" text-anchor="middle" fill="#14532d" font-weight="bold" font-size="15">TN</text>
  <text x="335" y="238" text-anchor="middle" fill="#166534" font-size="12">True Negative</text>
  <text x="335" y="255" text-anchor="middle" fill="#166534" font-size="11">correctly said: healthy</text>

</svg>`
A False Positive is a false alarm — the model said positive, but it was wrong. Also called a Type I error.
False Negatives
html`<svg width="460" height="300" font-family="inherit" font-size="14">

  <!-- Predicted axis label -->
  <text x="270" y="30" text-anchor="middle" fill="#334155" font-weight="bold" font-size="15">Predicted</text>
  <text x="185" y="68" text-anchor="middle" fill="#64748b">Positive</text>
  <text x="355" y="68" text-anchor="middle" fill="#64748b">Negative</text>

  <!-- Actual axis label -->
  <text x="38" y="175" text-anchor="middle" fill="#334155" font-weight="bold" font-size="15"
        transform="rotate(-90, 38, 175)">Actual</text>
  <text x="80" y="148" text-anchor="middle" fill="#64748b">Positive</text>
  <text x="80" y="238" text-anchor="middle" fill="#64748b">Negative</text>

  <!-- grid -->
  <rect x="110" y="78" width="300" height="190" rx="6" fill="none" stroke="#e2e8f0" stroke-width="1.5"/>
  <line x1="110" y1="173" x2="410" y2="173" stroke="#e2e8f0" stroke-width="1.5"/>
  <line x1="260" y1="78"  x2="260" y2="268" stroke="#e2e8f0" stroke-width="1.5"/>

  <!-- TP -->
  <rect x="113" y="81" width="144" height="89" rx="4" fill="#dcfce7" stroke="#16a34a" stroke-width="1.5"/>
  <text x="185" y="122" text-anchor="middle" fill="#14532d" font-weight="bold" font-size="15">TP</text>
  <text x="185" y="143" text-anchor="middle" fill="#166534" font-size="12">True Positive</text>
  <text x="185" y="160" text-anchor="middle" fill="#166534" font-size="11">correctly said: sick</text>

  <!-- FN -->
  <rect x="263" y="81" width="144" height="89" rx="4" fill="#fee2e2" stroke="#dc2626" stroke-width="1.5"/>
  <text x="335" y="122" text-anchor="middle" fill="#7f1d1d" font-weight="bold" font-size="15">FN</text>
  <text x="335" y="143" text-anchor="middle" fill="#991b1b" font-size="12">False Negative</text>
  <text x="335" y="160" text-anchor="middle" fill="#991b1b" font-size="11">said healthy — actually sick</text>

  <!-- FP -->
  <rect x="113" y="176" width="144" height="89" rx="4" fill="#fee2e2" stroke="#dc2626" stroke-width="1.5"/>
  <text x="185" y="217" text-anchor="middle" fill="#7f1d1d" font-weight="bold" font-size="15">FP</text>
  <text x="185" y="238" text-anchor="middle" fill="#991b1b" font-size="12">False Positive</text>
  <text x="185" y="255" text-anchor="middle" fill="#991b1b" font-size="11">said sick — actually healthy</text>

  <!-- TN -->
  <rect x="263" y="176" width="144" height="89" rx="4" fill="#dcfce7" stroke="#16a34a" stroke-width="1.5"/>
  <text x="335" y="217" text-anchor="middle" fill="#14532d" font-weight="bold" font-size="15">TN</text>
  <text x="335" y="238" text-anchor="middle" fill="#166534" font-size="12">True Negative</text>
  <text x="335" y="255" text-anchor="middle" fill="#166534" font-size="11">correctly said: healthy</text>

</svg>`
A False Negative is a missed case — the model said negative, but it was wrong. Also called a Type II error.
The Confusion Matrix — With Numbers
Disease screening example: 1000 patients, disease prevalence 1%
html`<svg width="460" height="300" font-family="inherit" font-size="14">

  <!-- Predicted axis label -->
  <text x="270" y="30" text-anchor="middle" fill="#334155" font-weight="bold" font-size="15">Predicted</text>
  <text x="185" y="68" text-anchor="middle" fill="#64748b">Positive</text>
  <text x="355" y="68" text-anchor="middle" fill="#64748b">Negative</text>

  <!-- Actual axis label -->
  <text x="38" y="175" text-anchor="middle" fill="#334155" font-weight="bold" font-size="15"
        transform="rotate(-90, 38, 175)">Actual</text>
  <text x="80" y="148" text-anchor="middle" fill="#64748b">Positive</text>
  <text x="80" y="238" text-anchor="middle" fill="#64748b">Negative</text>

  <!-- grid -->
  <rect x="110" y="78" width="300" height="190" rx="6" fill="none" stroke="#e2e8f0" stroke-width="1.5"/>
  <line x1="110" y1="173" x2="410" y2="173" stroke="#e2e8f0" stroke-width="1.5"/>
  <line x1="260" y1="78"  x2="260" y2="268" stroke="#e2e8f0" stroke-width="1.5"/>

  <!-- TP -->
  <rect x="113" y="81" width="144" height="89" rx="4" fill="#dcfce7" stroke="#16a34a" stroke-width="1.5"/>
  <text x="185" y="115" text-anchor="middle" fill="#14532d" font-weight="bold" font-size="22">0</text>
  <text x="185" y="138" text-anchor="middle" fill="#14532d" font-size="12">TP</text>
  <text x="185" y="158" text-anchor="middle" fill="#166534" font-size="11">correctly said: sick</text>

  <!-- FN -->
  <rect x="263" y="81" width="144" height="89" rx="4" fill="#fee2e2" stroke="#dc2626" stroke-width="1.5"/>
  <text x="335" y="115" text-anchor="middle" fill="#7f1d1d" font-weight="bold" font-size="22">10</text>
  <text x="335" y="138" text-anchor="middle" fill="#7f1d1d" font-size="12">FN</text>
  <text x="335" y="158" text-anchor="middle" fill="#991b1b" font-size="11">missed sick patients</text>

  <!-- FP -->
  <rect x="113" y="176" width="144" height="89" rx="4" fill="#fee2e2" stroke="#dc2626" stroke-width="1.5"/>
  <text x="185" y="210" text-anchor="middle" fill="#7f1d1d" font-weight="bold" font-size="22">0</text>
  <text x="185" y="233" text-anchor="middle" fill="#7f1d1d" font-size="12">FP</text>
  <text x="185" y="253" text-anchor="middle" fill="#991b1b" font-size="11">false alarms</text>

  <!-- TN -->
  <rect x="263" y="176" width="144" height="89" rx="4" fill="#dcfce7" stroke="#16a34a" stroke-width="1.5"/>
  <text x="335" y="210" text-anchor="middle" fill="#14532d" font-weight="bold" font-size="22">990</text>
  <text x="335" y="233" text-anchor="middle" fill="#14532d" font-size="12">TN</text>
  <text x="335" y="253" text-anchor="middle" fill="#166534" font-size="11">correctly said: healthy</text>

</svg>`
Accuracy = 990/1000 = 99% — but the model found zero sick patients. Every sick person was missed.
Precision — Don’t Cry Wolf
- Of everything the model predicted as positive, how many actually were?
\[\text{Precision} = \frac{TP}{TP + FP}\]
- High precision → few false alarms
- When false alarms are costly: spam filters, content moderation
- Example: flagging a professor’s email as spam has a real cost
Recall — Don’t Miss Anyone
- Of everything that was actually positive, how many did the model catch?
\[\text{Recall} = \frac{TP}{TP + FN}\]
- High recall → few missed cases
- When missing a case is catastrophic: disease screening, fraud detection
- Example: missing a cancer diagnosis has a far higher cost than a false alarm
The Precision–Recall Trade-Off
html`<svg width="660" height="220" font-family="inherit" font-size="14">

  <!-- Left: high recall low precision -->
  <rect x="20" y="20" width="285" height="180" rx="10" fill="#fef9c3" stroke="#ca8a04" stroke-width="2"/>
  <text x="163" y="52" text-anchor="middle" font-weight="bold" fill="#78350f" font-size="15">High Recall</text>
  <text x="163" y="72" text-anchor="middle" fill="#92400e">catch everything,</text>
  <text x="163" y="90" text-anchor="middle" fill="#92400e">accept more false alarms</text>

  <text x="163" y="120" text-anchor="middle" fill="#b45309" font-size="12">↑ TP   ↑ FP   ↓ FN</text>

  <text x="163" y="150" text-anchor="middle" fill="#78350f" font-size="12" font-style="italic">disease screening</text>
  <text x="163" y="170" text-anchor="middle" fill="#78350f" font-size="12" font-style="italic">fraud detection</text>
  <text x="163" y="190" text-anchor="middle" fill="#78350f" font-size="12" font-style="italic">content safety filters</text>

  <!-- right: high precision low recall -->
  <rect x="355" y="20" width="285" height="180" rx="10" fill="#dbeafe" stroke="#2563eb" stroke-width="2"/>
  <text x="498" y="52" text-anchor="middle" font-weight="bold" fill="#1e3a8a" font-size="15">High Precision</text>
  <text x="498" y="72" text-anchor="middle" fill="#1e40af">only flag when confident,</text>
  <text x="498" y="90" text-anchor="middle" fill="#1e40af">accept more missed cases</text>

  <text x="498" y="120" text-anchor="middle" fill="#1d4ed8" font-size="12">↑ TP   ↓ FP   ↑ FN</text>

  <text x="498" y="150" text-anchor="middle" fill="#1e3a8a" font-size="12" font-style="italic">spam filters</text>
  <text x="498" y="170" text-anchor="middle" fill="#1e3a8a" font-size="12" font-style="italic">recommendation systems</text>
  <text x="498" y="190" text-anchor="middle" fill="#1e3a8a" font-size="12" font-style="italic">search ranking</text>

</svg>`
Improving one tends to hurt the other. Which matters more depends entirely on the cost of each type of error in your domain.
F1 Score — Balancing Both
- Sometimes you need one number that respects both precision and recall
- The F1 score is their harmonic mean:
\[F_1 = 2 \cdot \frac{\text{Precision} \times \text{Recall}}{\text{Precision} + \text{Recall}}\]
- Harmonic mean punishes extreme imbalance — a model with precision=1.0 and recall=0.0 gets F1=0
- Use F1 when both false positives and false negatives matter
- Use precision or recall alone when one error type clearly dominates
Evaluating ML Models: Regression
When the Output Is a Number
- Classification asks: which category?
- Regression asks: how much?
- How many viewers will this stream get?
- How long will a user session last?
- What will the engagement score be?
- We can’t use accuracy — there’s no “right or wrong”, only how far off we were
- We need metrics that measure error
The Residual — The Basic Unit of Error
{
  const w = 660, h = 260;
  const svg = d3.create("svg")
    .attr("width", w).attr("height", h)
    .style("font-family", "inherit");

  const pad = { l: 55, r: 30, t: 20, b: 40 };
  const pw = w - pad.l - pad.r;
  const ph = h - pad.t - pad.b;

  const xMin = 0, xMax = 10, yMin = 0, yMax = 100;
  const xS = v => pad.l + (v - xMin) / (xMax - xMin) * pw;
  const yS = v => pad.t + ph - (v - yMin) / (yMax - yMin) * ph;

  // axes
  svg.append("line").attr("x1", pad.l).attr("y1", pad.t + ph)
    .attr("x2", pad.l + pw).attr("y2", pad.t + ph)
    .attr("stroke", "#ccc").attr("stroke-width", 1.5);
  svg.append("line").attr("x1", pad.l).attr("y1", pad.t)
    .attr("x2", pad.l).attr("y2", pad.t + ph)
    .attr("stroke", "#ccc").attr("stroke-width", 1.5);

  svg.append("text").attr("x", pad.l + pw / 2).attr("y", h - 4)
    .attr("text-anchor", "middle").attr("font-size", 12).attr("fill", "#888")
    .text("Stream duration (hrs)");
  svg.append("text").attr("x", 14).attr("y", pad.t + ph / 2)
    .attr("text-anchor", "middle").attr("font-size", 12).attr("fill", "#888")
    .attr("transform", `rotate(-90, 14, ${pad.t + ph / 2})`)
    .text("Peak viewers (k)");

  // regression line: y = 10x + 10
  svg.append("line")
    .attr("x1", xS(0)).attr("y1", yS(10))
    .attr("x2", xS(9)).attr("y2", yS(100))
    .attr("stroke", "#3b82f6").attr("stroke-width", 2.5);

  // single point example
  const px = 5, py = 72;
  const pyHat = 10 * px + 10; // = 60

  // residual line
  svg.append("line")
    .attr("x1", xS(px)).attr("y1", yS(py))
    .attr("x2", xS(px)).attr("y2", yS(pyHat))
    .attr("stroke", "#f97316").attr("stroke-width", 2.5)
    .attr("stroke-dasharray", "5,3");

  // actual point
  svg.append("circle").attr("cx", xS(px)).attr("cy", yS(py))
    .attr("r", 7).attr("fill", "#6366f1");

  // predicted point on line
  svg.append("circle").attr("cx", xS(px)).attr("cy", yS(pyHat))
    .attr("r", 5).attr("fill", "#3b82f6").attr("stroke", "white").attr("stroke-width", 1.5);

  // labels
  svg.append("text").attr("x", xS(px) + 10).attr("y", yS(py) - 6)
    .attr("font-size", 12).attr("fill", "#4338ca").attr("font-weight", "bold")
    .text("Actual: 72k");

  svg.append("text").attr("x", xS(px) + 10).attr("y", yS(pyHat) + 4)
    .attr("font-size", 12).attr("fill", "#1d4ed8").attr("font-weight", "bold")
    .text("Predicted: 60k");

  svg.append("text").attr("x", xS(px) + 10).attr("y", yS((py + pyHat) / 2) + 4)
    .attr("font-size", 12).attr("fill", "#ea580c").attr("font-weight", "bold")
    .text("Residual: +12k");

  // legend
  svg.append("line").attr("x1", pad.l + 5).attr("y1", pad.t + 12)
    .attr("x2", pad.l + 30).attr("y2", pad.t + 12)
    .attr("stroke", "#3b82f6").attr("stroke-width", 2.5);
  svg.append("text").attr("x", pad.l + 35).attr("y", pad.t + 16)
    .attr("font-size", 12).attr("fill", "#555").text("Model prediction");

  svg.append("circle").attr("cx", pad.l + 160).attr("cy", pad.t + 12)
    .attr("r", 5).attr("fill", "#6366f1");
  svg.append("text").attr("x", pad.l + 170).attr("y", pad.t + 16)
    .attr("font-size", 12).attr("fill", "#555").text("Observed data");

  return svg.node();
}
Residual = Actual − Predicted. Positive means we underestimated. Negative means we overestimated.
Mean Squared Error (MSE)
- Average all the residuals — but they cancel out (positives and negatives balance)
- So we square each residual first, then average
\[MSE = \frac{1}{n}\sum_{i=1}^{n}(y_i - \hat{y}_i)^2\]
- Squaring does two things: removes the sign, and punishes large errors more
- A single bad prediction can dominate the MSE
Visualizing MSE — Squared Residuals
{
  const w = 660, h = 280;
  const svg = d3.create("svg")
    .attr("width", w).attr("height", h)
    .style("font-family", "inherit");

  const pad = { l: 55, r: 30, t: 20, b: 40 };
  const pw = w - pad.l - pad.r;
  const ph = h - pad.t - pad.b;

  const xMin = 0, xMax = 10, yMin = 0, yMax = 110;
  const xS = v => pad.l + (v - xMin) / (xMax - xMin) * pw;
  const yS = v => pad.t + ph - (v - yMin) / (yMax - yMin) * ph;

  const data = [
    [1, 28], [2, 32], [3, 42], [4, 48], [5, 72],
    [6, 68], [7, 82], [8, 90], [9, 96]
  ];
  const slope = 10, intercept = 10;
  const yHat = x => slope * x + intercept;

  // axes
  svg.append("line").attr("x1", pad.l).attr("y1", pad.t + ph)
    .attr("x2", pad.l + pw).attr("y2", pad.t + ph)
    .attr("stroke", "#ccc").attr("stroke-width", 1.5);
  svg.append("line").attr("x1", pad.l).attr("y1", pad.t)
    .attr("x2", pad.l).attr("y2", pad.t + ph)
    .attr("stroke", "#ccc").attr("stroke-width", 1.5);

  svg.append("text").attr("x", pad.l + pw / 2).attr("y", h - 4)
    .attr("text-anchor", "middle").attr("font-size", 12).attr("fill", "#888")
    .text("Stream duration (hrs)");

  // regression line
  svg.append("line")
    .attr("x1", xS(0)).attr("y1", yS(intercept))
    .attr("x2", xS(10)).attr("y2", yS(slope * 10 + intercept))
    .attr("stroke", "#3b82f6").attr("stroke-width", 2);

  // squared residual boxes + residual lines
  data.forEach(([x, y]) => {
    const yh = yHat(x);
    const res = Math.abs(y - yh);
    const boxSize = res * (ph / (yMax - yMin));
    const boxX = xS(x) - boxSize / 2;
    const boxY = Math.min(yS(y), yS(yh));

    svg.append("rect")
      .attr("x", boxX).attr("y", boxY)
      .attr("width", boxSize).attr("height", boxSize)
      .attr("fill", "#f97316").attr("opacity", 0.18)
      .attr("stroke", "#f97316").attr("stroke-width", 0.8);

    svg.append("line")
      .attr("x1", xS(x)).attr("y1", yS(y))
      .attr("x2", xS(x)).attr("y2", yS(yh))
      .attr("stroke", "#f97316").attr("stroke-width", 1.5)
      .attr("stroke-dasharray", "4,2");

    svg.append("circle").attr("cx", xS(x)).attr("cy", yS(y))
      .attr("r", 5).attr("fill", "#6366f1");
  });

  // legend
  svg.append("line").attr("x1", pad.l + 5).attr("y1", pad.t + 12)
    .attr("x2", pad.l + 30).attr("y2", pad.t + 12)
    .attr("stroke", "#3b82f6").attr("stroke-width", 2);
  svg.append("text").attr("x", pad.l + 35).attr("y", pad.t + 16)
    .attr("font-size", 12).attr("fill", "#555").text("Model");

  svg.append("circle").attr("cx", pad.l + 135).attr("cy", pad.t + 12)
    .attr("r", 5).attr("fill", "#6366f1");
  svg.append("text").attr("x", pad.l + 145).attr("y", pad.t + 16)
    .attr("font-size", 12).attr("fill", "#555").text("Observed");

  svg.append("rect").attr("x", pad.l + 225).attr("y", pad.t + 5)
    .attr("width", 14).attr("height", 14)
    .attr("fill", "#f97316").attr("opacity", 0.3).attr("stroke", "#f97316");
  svg.append("text").attr("x", pad.l + 244).attr("y", pad.t + 16)
    .attr("font-size", 12).attr("fill", "#555").text("Squared residual");

  return svg.node();
}
The area of each orange square is the squared error for that prediction. MSE is the average of all those areas.
Root Mean Squared Error (RMSE)
- MSE is in squared units — hard to interpret directly
- If viewers are in thousands, MSE is in thousands squared
- Take the square root to get back to the original units
\[RMSE = \sqrt{\frac{1}{n}\sum_{i=1}^{n}(y_i - \hat{y}_i)^2}\]
- RMSE = 8k means predictions are off by roughly 8,000 viewers on average
- Same scale as the data — directly interpretable
- Still sensitive to large errors because of the squaring step
Mean Absolute Error (MAE)
- Instead of squaring, just take the absolute value of each residual
\[MAE = \frac{1}{n}\sum_{i=1}^{n}|y_i - \hat{y}_i|\]
- Every error counts equally — no extra punishment for large ones
- More robust when your data has outliers
- Easier to explain: MAE = 8k means predictions are off by 8,000 viewers on average
MSE vs MAE — The Outlier Problem
{
  const w = 660, h = 240;
  const svg = d3.create("svg")
    .attr("width", w).attr("height", h)
    .style("font-family", "inherit");

  // two panels
  const panels = [
    { x: 20,  label: "No outlier", errors: [5, 8, 6, 7, 9, 5, 6], color: "#6366f1" },
    { x: 340, label: "One outlier (80k off)", errors: [5, 8, 6, 7, 9, 5, 80], color: "#ef4444" }
  ];

  panels.forEach(({ x, label, errors, color }) => {
    const mae = errors.reduce((s, e) => s + e, 0) / errors.length;
    const mse = errors.reduce((s, e) => s + e * e, 0) / errors.length;
    const rmse = Math.sqrt(mse);

    // panel box
    svg.append("rect").attr("x", x).attr("y", 10)
      .attr("width", 300).attr("height", 210).attr("rx", 10)
      .attr("fill", color + "0d").attr("stroke", color).attr("stroke-width", 1.5);

    svg.append("text").attr("x", x + 150).attr("y", 38)
      .attr("text-anchor", "middle").attr("font-weight", "bold")
      .attr("fill", color).attr("font-size", 14).text(label);

    // bar chart of errors
    const barW = 26, barPad = 4;
    const maxErr = 90;
    const barAreaH = 100;
    const barBaseY = 155;

    errors.forEach((e, i) => {
      const bh = (e / maxErr) * barAreaH;
      const bx = x + 20 + i * (barW + barPad);
      const isOutlier = e === 80;
      svg.append("rect")
        .attr("x", bx).attr("y", barBaseY - bh)
        .attr("width", barW).attr("height", bh).attr("rx", 3)
        .attr("fill", isOutlier ? "#ef4444" : color)
        .attr("opacity", isOutlier ? 1 : 0.6);
    });

    // axis line
    svg.append("line").attr("x1", x + 15).attr("y1", 155)
      .attr("x2", x + 285).attr("y2", 155)
      .attr("stroke", "#ccc").attr("stroke-width", 1);

    // metrics
    svg.append("text").attr("x", x + 150).attr("y", 180)
      .attr("text-anchor", "middle").attr("font-size", 13).attr("fill", "#334155")
      .text(`MAE = ${mae.toFixed(1)}k`);
    svg.append("text").attr("x", x + 150).attr("y", 200)
      .attr("text-anchor", "middle").attr("font-size", 13).attr("fill", "#334155")
      .text(`RMSE = ${rmse.toFixed(1)}k`);
  });

  return svg.node();
}
One large outlier barely moves MAE — but explodes RMSE. Choose based on whether outliers represent real signal or noise.
Choosing the Right Regression Metric
| Metric | Penalizes outliers? | Units | Use when… |
|---|---|---|---|
| MAE | No | Same as data | Outliers are noise; you want robustness |
| MSE | Yes (heavily) | Squared | Large errors are especially costly |
| RMSE | Yes | Same as data | Large errors matter; you want interpretability |
There is no universally best metric. The choice depends on what kinds of errors hurt most in your domain.
IAT 461 · Data Science for Human-Centered Systems · Summer 2026